-
Vijit
- November 9, 2026
- No categories assigned.
- No Comments
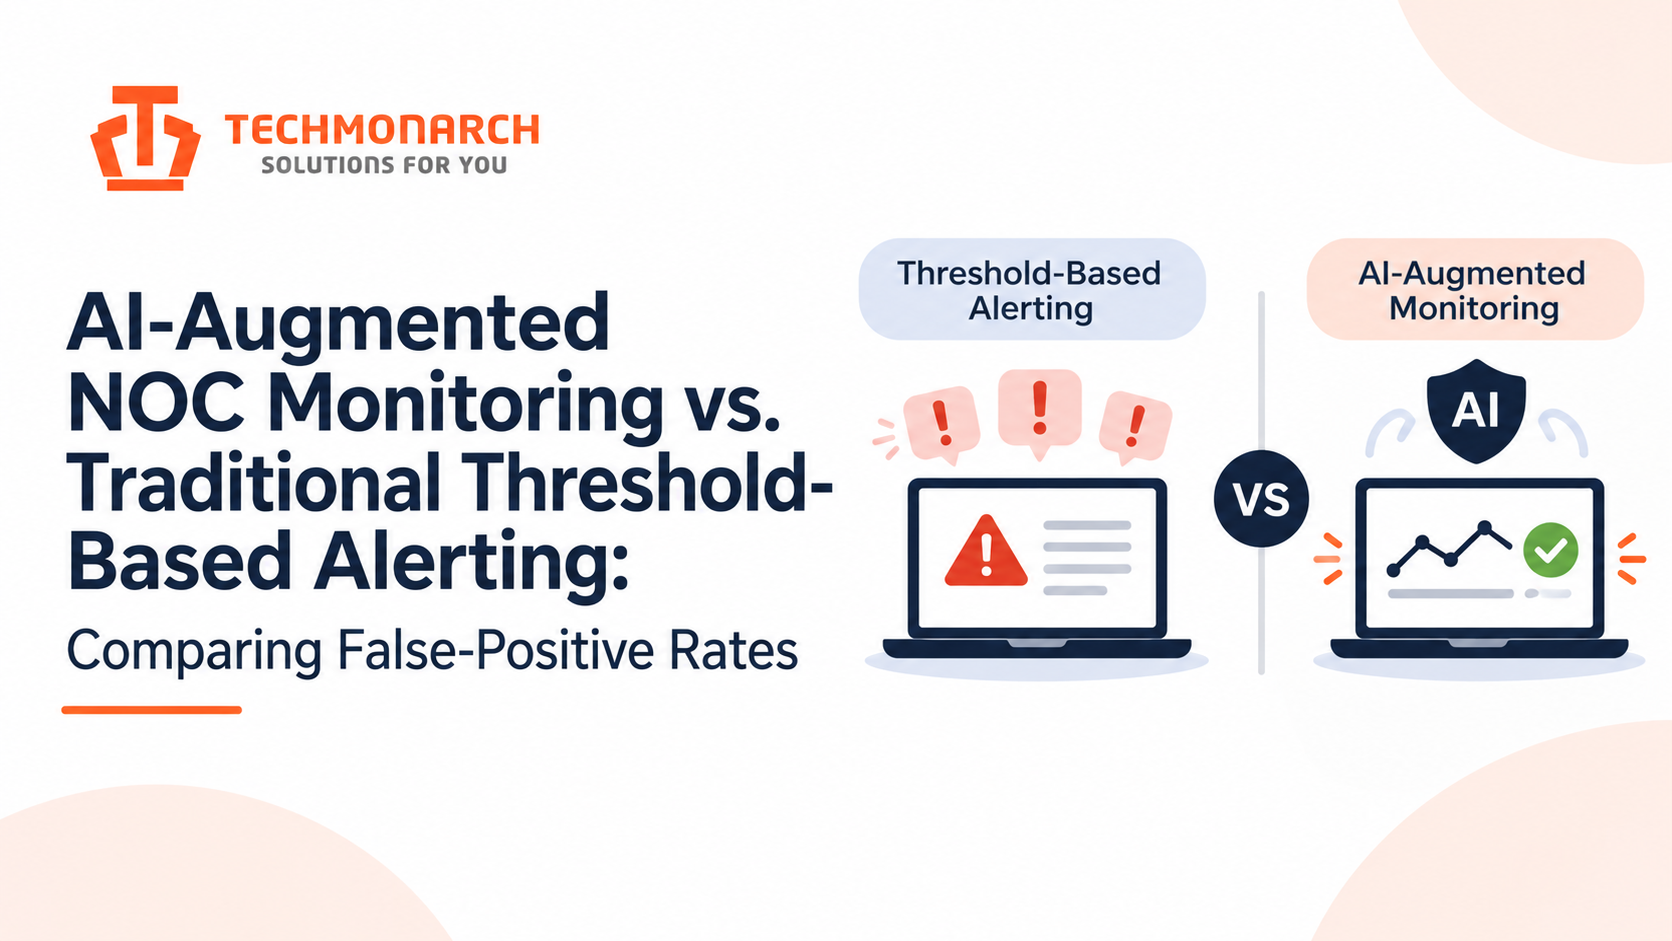
Every vendor selling AI-driven monitoring quotes a noise-reduction figure, usually somewhere between fifty and ninety percent. Almost none of them tell you how the number was measured, what was counted as noise, or what got suppressed along the way. If you run NOC operations for MSP clients, or you’re evaluating a white-label NOC partner who does, that gap matters. A false-positive rate is only useful if you know the denominator.
This isn’t an argument for or against AI in the NOC. It’s a look at how false positives actually arise in each model, what the trade-offs are, and how to measure the difference in your own environment instead of trusting a slide.
First, Define What You’re Counting
“False positive” gets used loosely in monitoring. In a security tool it means a benign event flagged as malicious. In a NOC it’s messier. An alert can be technically correct and still be noise: a CPU spike that resolves in ninety seconds, a disk at 85% on a volume that grows slowly and has months of headroom, a link flap during a scheduled maintenance window.
For operational purposes, the most useful metric is the actionable-alert rate: the share of alerts that required a human or automated response. Everything else is noise, whether or not the underlying measurement was accurate. A threshold alert that fired correctly and led to no action still cost someone triage time.
You also need the opposite number, which most comparisons skip: missed incidents, meaning real problems that produced no alert or whose alert was suppressed. A system that cuts noise by suppressing everything looks excellent until the day it hides the outage.
Why Threshold Alerting Generates Noise
Static thresholds are simple and predictable, and that’s their appeal. Set CPU above 90% for five minutes, disk above 85%, latency above 150 milliseconds, and the behavior is easy to explain to a client and easy to audit.
The problem is that a fixed number can’t know context. A file server at 90% CPU during the nightly backup is normal. The same reading at 2 p.m. on a Tuesday is not. A threshold has no concept of time of day, day of week, seasonal load, or the particular habits of one client’s environment.
The usual response is to tune thresholds per device, per client, per time window. That works for a while, then decays. Environments change, new workloads arrive, and the tuning work is rarely owned by anyone. Many MSPs end up with a default template applied everywhere, which produces the same noisy alerts across hundreds of endpoints.
There’s also the volume problem. One underlying fault, like a failed switch, produces dozens of alerts from every device behind it. Threshold alerting treats each as an independent event, so the NOC receives forty tickets for one incident. The effect is cumulative: the more noise, the slower the response to the alert that matters, and alert fatigue sets in long before anyone formally measures it.
Where AI-Augmented Monitoring Reduces False Positives
The label covers several different techniques, and it helps to separate them, because they behave differently.
Dynamic baselining. Instead of a fixed number, the system learns what normal looks like for a metric on a particular device across time of day and day of week. A backup-window CPU spike stops alerting because it’s expected. Where this works, it directly removes a big category of threshold noise.
Event correlation. Related alerts get grouped into a single incident. The forty alerts behind the failed switch become one ticket with a probable root cause. This is usually where the largest volume reduction comes from, and it’s a different mechanism from reducing false positives in the strict sense. The alerts weren’t wrong, they were redundant.
Anomaly detection. Statistical or machine-learning models flag behavior that deviates from the learned pattern, even when no threshold has been crossed. This is the one that can catch problems thresholds miss, like a slow memory leak or gradually rising error rates.
Automated enrichment and remediation. Not strictly false-positive reduction, but related: the system attaches context, checks whether the condition has already cleared, or runs a safe fix before a ticket is created.
If you want the background on how these fit together, our post on what AIOps is in IT operations walks through the basics.
An Illustrative Comparison
Here’s a simplified model. The inputs are my assumptions for illustration, so replace them with your own alert data before drawing conclusions.
Assume an MSP NOC monitoring a mid-sized client base, producing alerts across servers, network devices, and endpoints.
Threshold-based alerting
- 12,000 alerts per month
- 18% actionable, which is 2,160 alerts
- 9,840 noise alerts, at about 3 minutes of triage each, which is roughly 490 hours per month
AI-augmented monitoring (dynamic baselines plus correlation)
- 3,900 alerts or incidents per month
- 54% actionable, which is 2,106
- 1,794 noise alerts at 3 minutes each, which is roughly 90 hours per month
On those assumptions, noise falls by more than 80%, and the NOC recovers about 400 hours a month of triage time. Notice what happened to the actionable number, though. It dropped from 2,160 to 2,106. Some of that is correlation merging several actionable alerts into one incident, which is the intended behavior. But 54 fewer actionable alerts is also exactly the kind of gap you need to explain, not assume. Were they merged duplicates, or real events that got suppressed?
That’s the right question to ask of any noise-reduction claim: not just how many alerts went away, but what happened to the ones that mattered.
Where AI Monitoring Makes Things Worse
It isn’t a clean win, and anyone who tells you it is hasn’t run it in production.
Cold start. Dynamic baselines need history. A new client, a new server, or a freshly migrated workload has no baseline, so the model either stays quiet when it shouldn’t or alerts erratically while it learns. Many tools need weeks of data before they behave well.
Drift and legitimate change. A baseline learned from last quarter’s pattern may flag this quarter’s growth as anomalous. Seasonal businesses, such as retail, education, and tax practices, can generate false anomalies at every peak unless the model accounts for it.
Opaque suppression. When a rules-based alert doesn’t fire, you can trace why. When a model decides not to alert, the reason may be a score you can’t inspect. That makes missed incidents harder to diagnose and harder to defend to a client after an outage.
Correlation errors. Grouping the wrong alerts together can bury a separate, real problem inside an unrelated incident. This is rare, but when it happens, the incident review is awkward.
Over-automation. Pushing automated remediation too far removes the human judgment that catches the odd cases. We’ve written about the hidden costs of over-automation and why the human element still matters in the NOC, and it applies directly here: the goal is fewer wasted human minutes, not fewer humans in the loop for decisions that need judgment.
The Hybrid Most Mature NOCs End Up With
In practice, strong NOCs don’t choose one or the other. They match the method to the metric.
Use static thresholds where a hard limit is the point: disk at 95%, certificate expiring in seven days, a service that must be running, a backup that failed. These conditions don’t depend on context, and a model adds nothing but opacity.
Use dynamic baselines and anomaly detection for metrics where normal varies: traffic volume, latency, error rates, login patterns, resource usage on shared systems.
Use correlation everywhere, because redundant alerts are noise regardless of how each one was generated.
Keep a human review loop. Someone should sample suppressed and merged alerts weekly, compare them against actual incidents, and adjust. The review is what turns an AI tool into a monitored system rather than a black box.
How to Measure It in Your Environment
Before you adopt any tooling, or before you accept a partner’s numbers, pull your own baseline.
- Actionable-alert rate. Over thirty days, classify a sample of alerts as actionable or not. Do this per alert type, not in aggregate, so you can see where the noise concentrates.
- Alerts per incident. Count how many alerts typically roll up into one real incident. A high ratio points to correlation as your biggest opportunity.
- Missed-incident review. After every outage or client-reported issue, check whether an alert existed and whether it was acted on or suppressed.
- Time to acknowledge. Noise shows up as slower acknowledgment of the alerts that matter. Track it by severity.
- Triage hours spent on non-actionable alerts. This converts a percentage into a cost you can compare against a tool or partner fee. Our breakdown of the key metrics every advanced NOC professional should track covers how to structure these.
If a vendor or partner can’t show you the same numbers from their own operations, treat their noise-reduction claim as marketing.
Making the Call
If your NOC is drowning in redundant alerts from a single fault, start with correlation. It’s the fastest win and the lowest risk. If your noise comes mostly from context-blind thresholds on variable metrics, add dynamic baselines for those metrics only, and leave your hard-limit alerts alone. And whatever you adopt, plan for the cold-start period and keep humans reviewing what gets suppressed.
For MSPs that would rather not build and tune this themselves, a white-label partner running mature monitoring can carry that work, provided they can show you actionable-alert rates and missed-incident reviews from real operations. Our monitoring and event management service is built around that kind of tuned, measured alerting, and it’s worth comparing against whatever your current setup is producing.
Measure before you switch, measure after, and count the incidents that never raised an alert. That last number is the one that decides whether the tool is working.
Reference
- How AIOps Transforms Network Anomaly Detection from Threshold Alerts to Predictive Intelligence — https://ennetix.com/how-aiops-transforms-network-anomaly-detection-from-threshold-alerts-to-predictive-intelligence/
- Alert Fatigue in NOC and SOC Teams: How AI Correlation Ends the Noise in 2026 — https://ennetix.com/alert-fatigue-in-noc-and-soc-teams-how-ai-correlation-ends-the-noise-in-2026/
- AIOps for Incident Management — https://coralogix.com/ai-blog/aiops-for-incident-management/
Reference 02
- How AIOps Improves Response Times in the NOC — https://www.bigpanda.io/blog/aiops-in-the-noc
- How AlertOps Cut Alert Noise by 70% for a Global NOC — https://alertops.com/blogs/alertops-reduces-alert-noise-noc/
- From Reactive to Predictive: How AI Is Rewriting the NOC Playbook — https://www.uctoday.com/security-compliance-risk/from-reactive-to-predictive-how-ai-is-rewriting-the-noc-playbook/
Recent Posts
- AI-Augmented NOC Monitoring vs. Traditional Threshold-Based Alerting: Comparing False-Positive Rates
- RMM-Native White-Label Support vs. Ticket-Only Outsourcing: Why Tool Access Changes the Math
- ISO 27001 vs. SOC 2 Type II: Which Certification Should You Actually Require From a White-Label Partner?
- White-Label Helpdesk vs. Hiring Your Own Tier-1 Team: A 3-Year TCO Model
- White-Label IT Service Delivery Explained
Recent Comments
- No comments to show